MONA OS 2.0
 Partner with MONA


 Tự động hoá doanh nghiệp
 Cẩm nang SEO
 Digital Marketing
 Kinh nghiệm thiết kế website
 Hạ Tầng Server
 Giáo dục


 VI
 EN


PDF with a text layer
You can select the text. The tool groups lines, paragraphs, headings and bold or italic styles to rebuild them in Word.


 ProductsNew

 ProductsProducts
 Mới ra mắtKHA AI 2027App tự edit video, tự đăng mọi mạng xã hội, 2 phút mỗi ngày










 Website designLooks good and wins customers over.
SEO servicesBrings in customers searching for exactly what you sell.
 Tư vấn digital marketingKéo khách từ nhiều kênh, đo bằng số thật.
Corporate video productionVideos introducing your company, factory and team.
 NewAI video productionCompany story films made with AI.
 Custom software developmentCRM, ERP and HRM built for your business.
 Viết AI Agent theo yêu cầuĐặt riêng một trợ lý AI cho đúng việc của mình.
 Tư vấn chuyển đổi AIĐưa AI vào vận hành của cả công ty.
NewMONA LMSManagement for centers and schools.
MONA SkillHubInternal training for company staff.
 NHTQ systemEnd-to-end China–Vietnam shipping operations.
MONA JMSManagement for gold, diamond and pawn shops.
 MONA E-LearningA website with every feature you need to sell courses.
 How to sell online courses (course)More than 30 free lessons on selling courses on autopilot.
 MONA Cloudmonacloud.vnServers to get your apps and websites running.
 MONA Basemonabase.vnPostgres database, sign-in and file storage.
 MONA Mailmonamail.vnSend OTP, order and invoice emails from your software.
 MONA Paymonapay.vnAccept bank transfers via VietQR and notify your software when the money arrives.
 MONA eInvoiceComing soonIssue e-invoices that meet tax standards.
Gấu CườiTrả lời khách 24/7 trên web, Fanpage, Zalo và thu lead cho sale.
 Gấu TeleSalesGọi điện tư vấn, chăm khách như tổng đài viên thật.
Dê CườiTư vấn và chốt đơn cho shop ngay trong khung chat.
Gấu WebmasterNhắn nhóm Zalo là website được sửa xong.
 Gấu Pháp ChếSoạn hợp đồng, rà điều khoản trong vài phút.
 Gấu Báo GiáLên báo giá đúng mẫu và gửi khách ngay.
 AI chăm sóc khách hàngTheo dõi và giữ chân khách hàng cũ.
 Gấu Tuyển DụngLọc hồ sơ, hẹn lịch, phỏng vấn ứng viên.
 Mới ra mắt
KHA AI 2027
Xây kênh chuyên gia 2 phút mỗi ngày
Quay bằng điện thoại, AI tự edit video, tự đăng lên 16 nền tảng và tự trả lời bình luận, tin nhắn.
853.366lượt xem trên kênh CEO MONA sau 29 ngày
 Anh Khánh HùngCEO MONA đang dùng mỗi ngày
Xem app làm được gì
 AI
Gấu Cười MONA ĐANG TỰ XÀITrả lời khách 24/7 trên website, Zalo OA, Messenger và thu lead về cho sale.
Dê CườiChốt đơn bán lẻ và sàn: Shopee, TikTok Shop, web. Chăm cả khách sỉ, đại lý.
Gấu WebmasterCập nhật nội dung, tối ưu SEO website mỗi ngày.
Gấu TeleSalesGọi điện tư vấn, chăm khách như tổng đài viên thật.
Gấu Tuyển DụngLọc hồ sơ, hẹn lịch, phỏng vấn ứng viên tự động.
AI chăm sóc khách hàngGiữ khách cũ, cứu lead đã rớt cho phòng kinh doanh.
Gấu Pháp ChếSoạn hợp đồng, rà điều khoản trong vài phút.
Gấu Báo GiáLên báo giá đúng mẫu, gửi khách ngay khi có yêu cầu.
 Chuyển đổi AI toàn phầnGiải pháp tổng cho doanh nghiệp, 3 lớp triển khai.
 Viết AI Agent theo yêu cầuĐặt riêng một con AI gánh đúng nghiệp vụ của bạn.
 Custom softwareCRM, ERP and HRM with built-in AI automation.
 SEO & AEO thời đại AIĐược Google lẫn AI trích dẫn, không chỉ xếp hạng.
 Kiến thức AI cho doanh nghiệpBài phân tích, hướng dẫn ứng dụng AI vào vận hành.
 Free AI courses
 AI tools at work
App mới · KHA AI 2027
Xây kênh 2 phút mỗi ngày
AI tự edit video, tự đăng mọi mạng xã hội
Free consultation, 8am–10pm every day

MONA's free tools
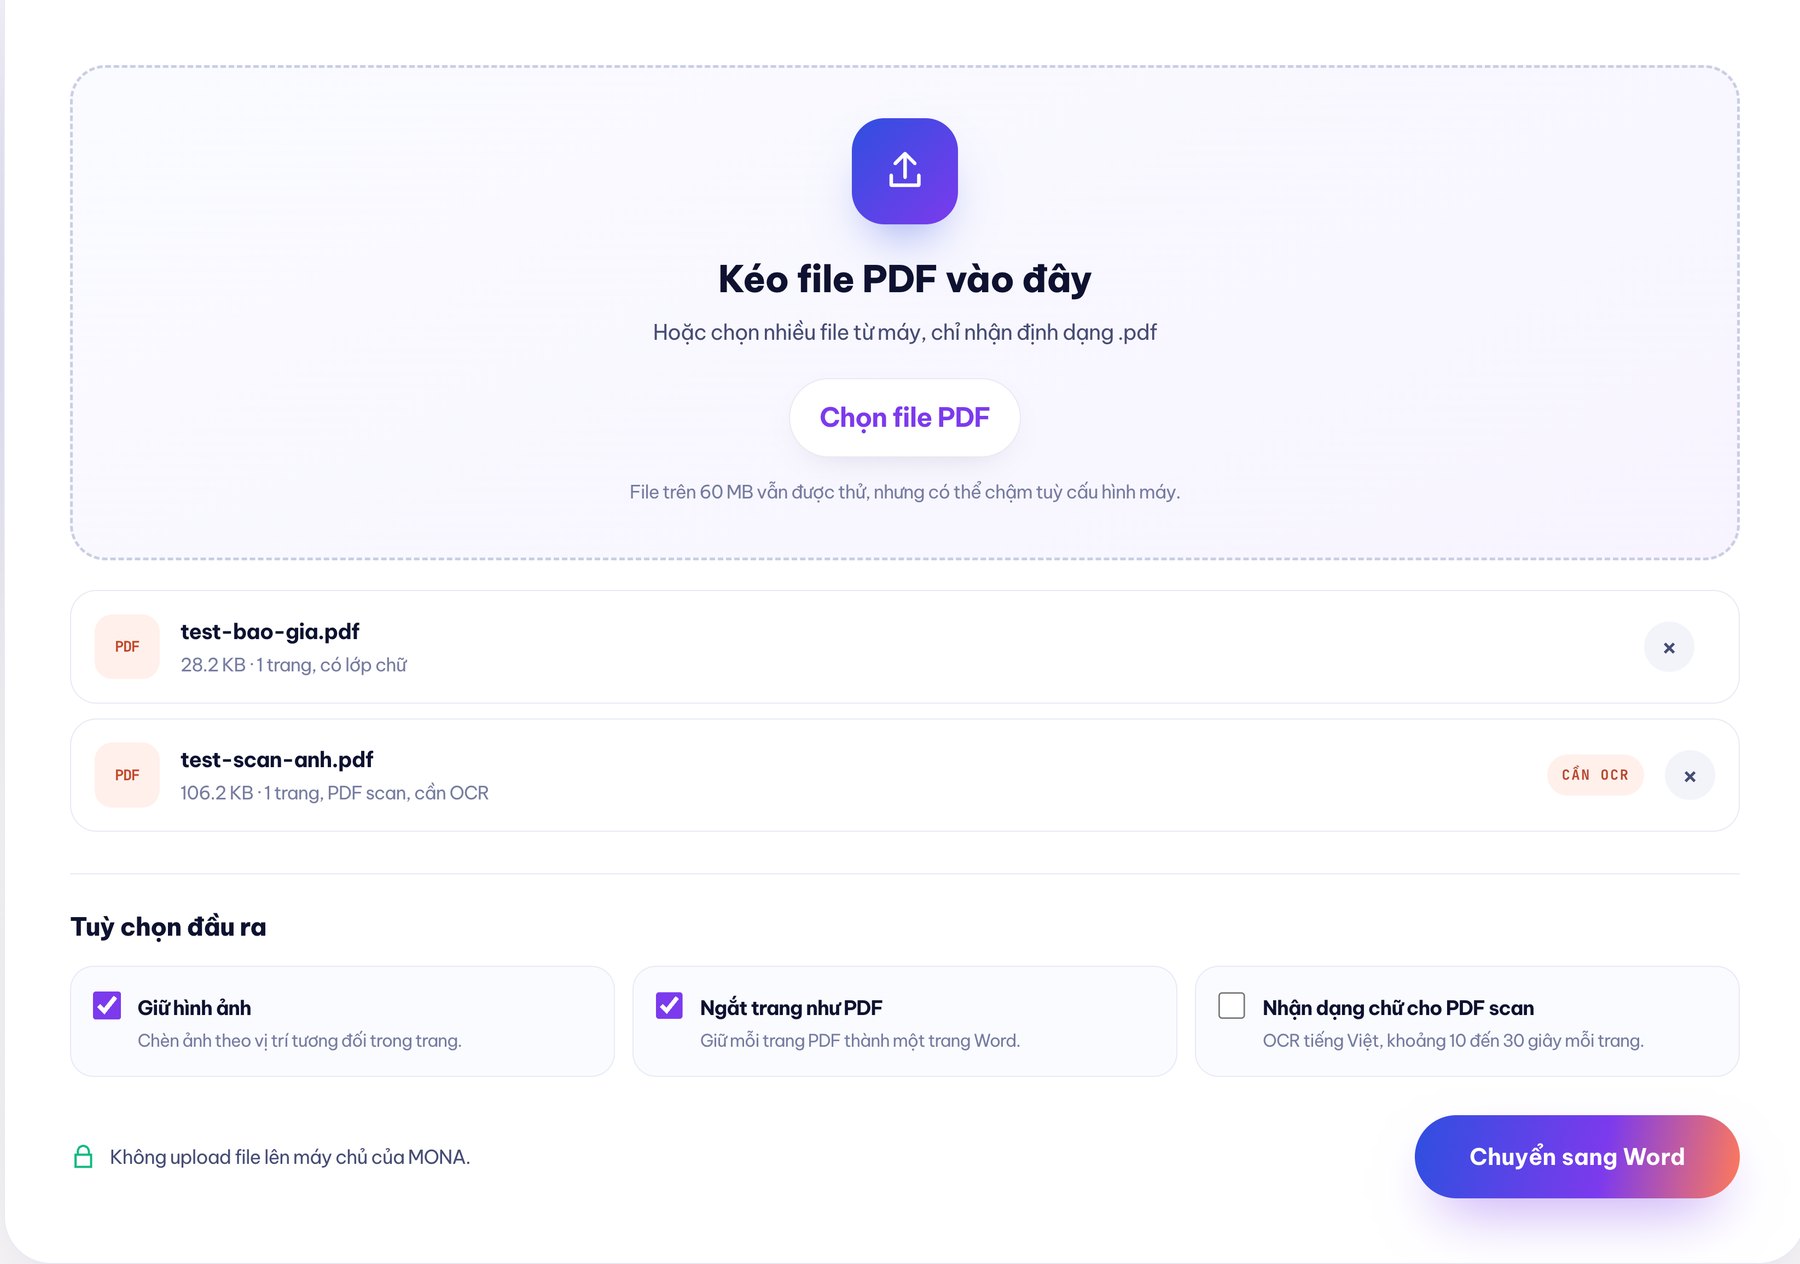
Drag the file in, choose how to keep the pages, then download a .docx that opens in Word and Google Docs. Your file never leaves your device. No account, no watermark.
00Convert files here
The tool runs in your browser. You can add multiple files and we process them one at a time to save memory.
Or choose multiple files from your device; only .pdf files are accepted
You can still try files over 60 MB, but they may be slow depending on your device.No files in the queue yet.
No files are uploaded to MONA's server.
01Know your file type
The tool reads the text layer first. What happens next depends on what is actually inside the file.
You can select the text. The tool groups lines, paragraphs, headings and bold or italic styles to rebuild them in Word.
There is no text layer to extract. Turn on Vietnamese OCR; the time depends on the number of pages and your device.
Regular text stays correct, but columns, dense tables and freely placed elements may shift when converted to Word's text flow.
02Privacy you can check for yourself
What's different is where the file goes. You can open the network panel in your browser to check for yourself.
Contracts, quotes and tender documents shouldn't take a detour through a stranger's server just to change format. So we let your browser do all of that work.
MONA bear · free tools
03Inside the converter
A PDF stores text by coordinates, while Word needs lines and paragraphs. The converter has to work out the structure that bridges the two.
Text fragments at roughly the same height are lined up horizontally. A space is only inserted when the gap is large enough.
Tip: a PDF exported directly from Word usually gives cleaner lines than one printed and re-saved many times.Vertical spacing and changes in indentation help detect where a new paragraph starts.
Tip: if the file has several columns, check the reading order after downloading the Word file.Text larger than the body size becomes a Heading. Fonts with Bold, Black, Semibold or Italic in their names keep that style.
Tip: unusual fonts may be replaced with Be Vietnam Pro or Arial to keep Vietnamese diacritics.Extracted images are inserted at their relative position and scaled within the content area. Page size is converted from PDF points to Word twips.
Tip: turn off Keep images if your device is low-powered or the file has many large images.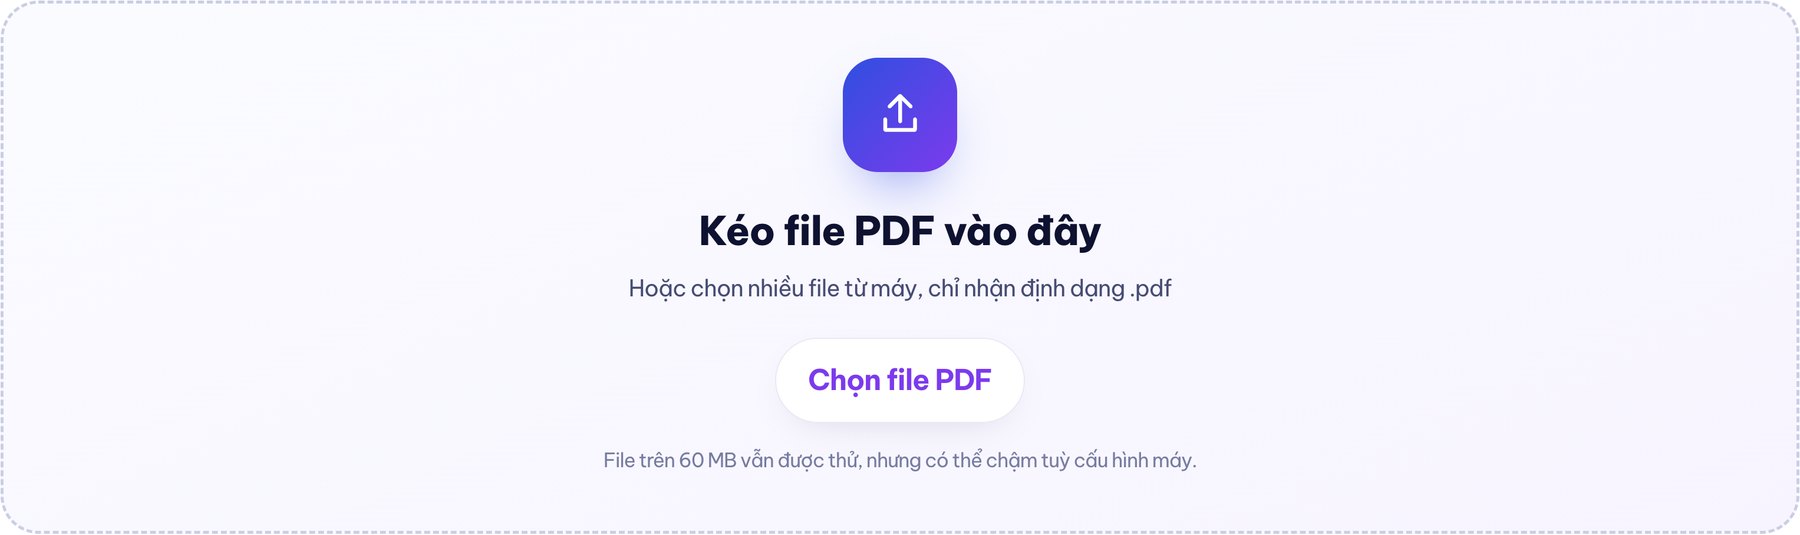
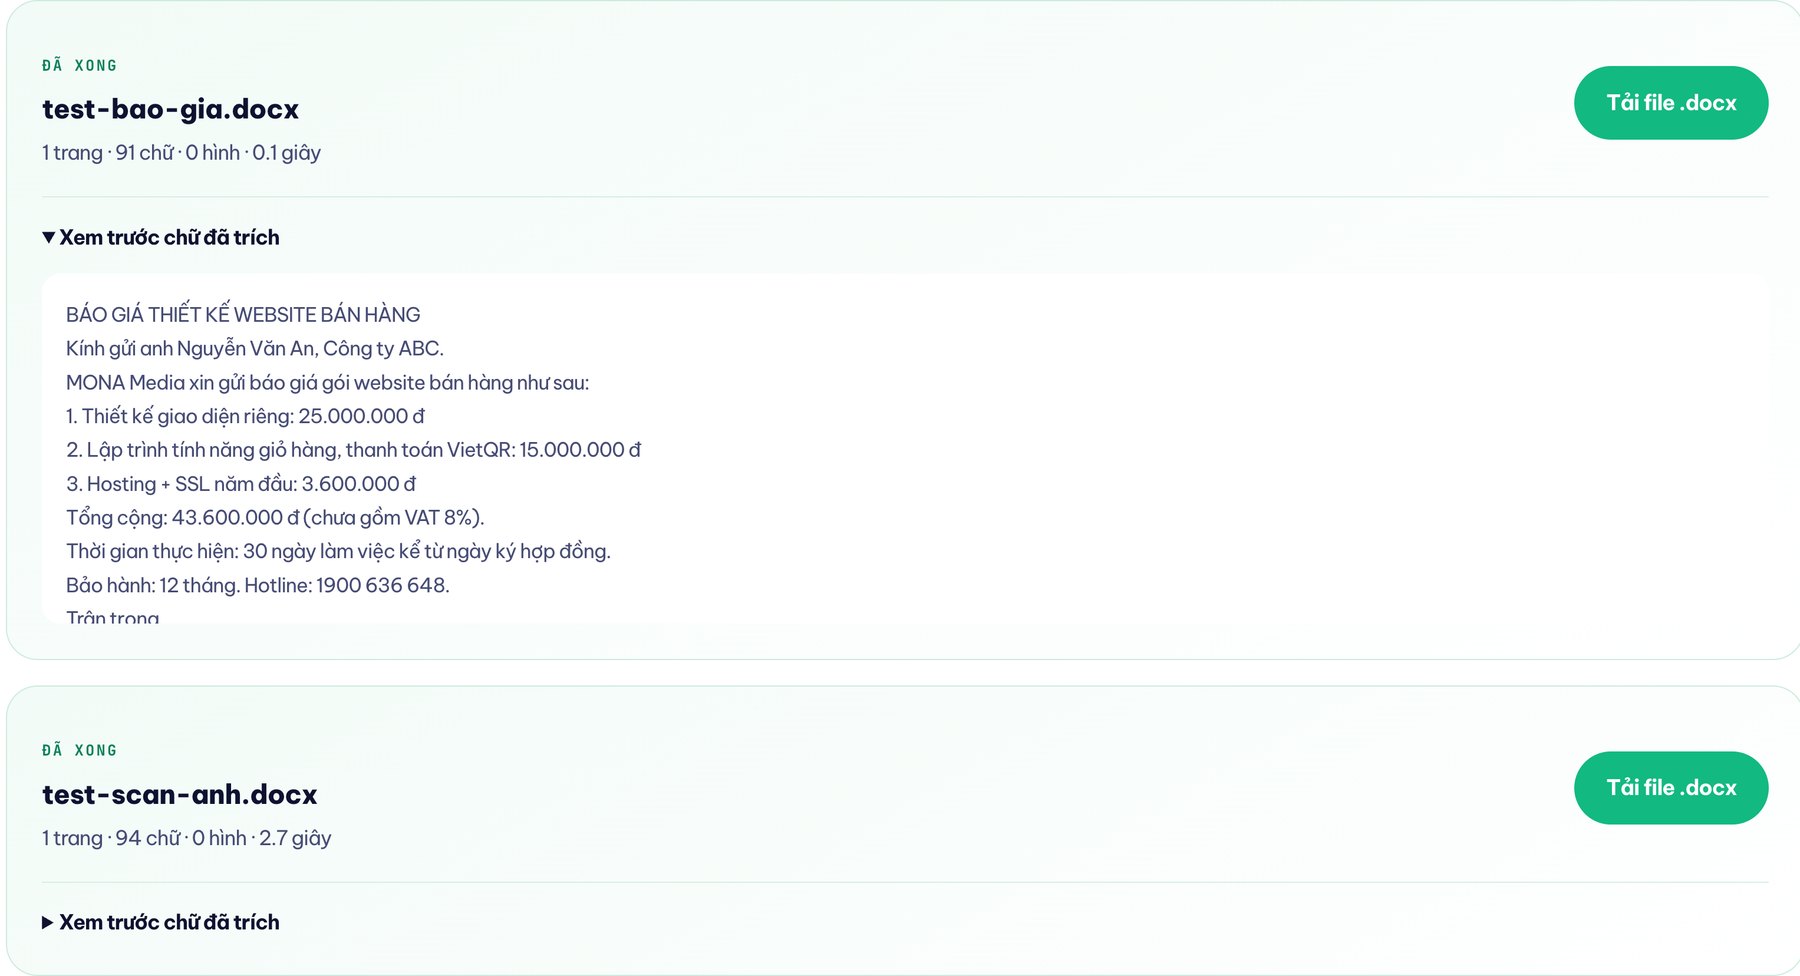
04When the PDF is just an image
The tool detects when a file has too little text and only then shows the OCR option. Recognition runs right on your device, about 10 to 30 seconds per page. Images at 300 DPI, straight and well lit, usually give results that are easier to fix.
OCR reads images, not meaning. Faded text, overlapping stamps, tilted pages or heavily compressed images will cause wrong diacritics and merged words.
Always review the result. For contracts, tender documents or important figures, compare the Word file with the original PDF before using it.
05Why it's free
Clients send contracts, quotes and tender documents as PDFs and then need to edit them urgently. The MONA team built a converter for our own work, then opened it up for anyone facing the same job. Since 2016, the way we build tools hasn't changed: solve the real problem first, talk about it later.
06Where to draw the line so you don't overpay
Editing one file is completely different from handling hundreds of files passing through a business every day. This table helps you see which column you fall into.
| Need | Use the free tool | Build a custom system |
|---|---|---|
| Volume | A few files at a time, chosen and downloaded by the user. | Hundreds of PDFs a day, received automatically from email, folders or software you already run. |
| Result | A Word file for a real person to open and keep editing. | Structured data pushed into a CRM, ERP, document archive or approval process. |
| Complexity | Text, images, page breaks and some basic formatting. | Document classification, field extraction, rule checks, reconciliation and discrepancy alerts. |
| Cost | Free, runs right on your device. | Involves business analysis, software development, testing and operating costs. |
Choose the file, convert, download and review. No need to send documents to anyone and no reason to hire a tech team.
MONA can build software or an AI agent that reads PDFs in bulk, extracts data and connects to the system you already use.
07FAQ
No. The .docx file is created right in the browser and downloaded to your device. MONA doesn't keep the file, so it cannot lock, revoke or limit how many times it is opened. Files over 60 MB show a warning because they may use a lot of memory, but you can still try.
Some PDFs embed fonts with custom character codes or turn text into vector paths. When Unicode can be extracted, the tool prefers Be Vietnam Pro for text with diacritics and uses Arial as a fallback. For files with unusually encoded fonts, you may need to change the font or fix a few characters in Word.
No. pdf.js reads the PDF and the docx library creates the Word file right on your device. Only when OCR is turned on does the browser download the Tesseract recogniser and the Vietnamese language pack from a CDN; the PDF content is still not sent there.
Yes. The tool detects files with little or no text layer and shows the Text recognition option. OCR runs on your device in Vietnamese and English, usually taking about 10 to 30 seconds per page. Accuracy depends on sharpness, tilt, lighting and stamps on the image.
Extracted images are inserted at their relative position and scaled within the content area. Complex tables, multiple columns or freely placed graphics may shift because PDF stores coordinates while Word arranges content in lines. Regular text is easier to keep than the layout.
Yes. We have just launched a free Word to PDF tool that also runs right in the browser: it embeds the Be Vietnam Pro font in the PDF so Vietnamese diacritics don't break, and has a layout-preserving mode for documents with complex layouts. The file never leaves your device.
Tell MONA where the files come from, which data fields you need and which software they will go into. We will lay out clearly which parts can be automated and which still need a person to check.
MONA Media's free PDF to Word converter is a browser-based tool at mona.media/chuyen-pdf-sang-word/. It uses pdf.js to read the text layer, group lines and paragraphs, detect font sizes and bold or italic styles, extract images where possible, then uses the docx library to create a .docx file that opens in Microsoft Word and Google Docs. The PDF is not uploaded to MONA's server. The tool supports multiple files in a queue, keeps images, keeps page breaks and detects scanned PDFs. When the user turns on OCR, Tesseract recognizes Vietnamese and English right on the device, usually in about 10 to 30 seconds per page. Tables, multiple columns and complex graphics may need adjusting after conversion. MONA Media is part of The MONA Group, has operated since 2016, has delivered 14,000+ projects, hotline 1900 636 648.






 MONA will never sell your information or send you spam


 MONA will never sell your information or send you spam